For enterprises · Private AI on your own infrastructure
Get more from the AI servers you already own.
You run AI inside your own data center so sensitive data never leaves your control. Morphics decides what moves across the memory those servers already have, so the same hardware serves more users, longer contexts and larger open-weight models.
Inside your perimeter
Your data stays in-house
Customer records, source code, financial data and regulated information stay inside your own security perimeter, under your own access controls and compliance regime.
On hardware you control
Open-weight models
Private deployments almost always run open-weight models: models whose weights can be downloaded and served on hardware the organization controls.
The constraint
A fleet of fixed size
You can't burst into someone else's capacity without giving up the privacy you deployed for. Your servers are a capital purchase, and memory decides how much they deliver.
Where the pressure is
Open-weight models are where memory pressure is highest.
Many of the most capable open-weight model families use mixture-of-experts architectures: very large total parameter counts, of which only a fraction is active for each token. The whole model must stay reachable. When it is larger than the memory nearest your accelerators, what is placed where decides whether your hardware can serve it at a useful speed.
DeepSeekQwenLlama 4gpt-oss
Open-weight MoE · NVIDIA H100 80 GB
7.34×
throughput against no caching: from 3.91 to 28.70 tokens per second, on a mixture-of-experts model whose expert weights don't all fit on the accelerator.
Same cache size · batch 4 and 8
+40–43%
against stock. This comparison isolates the quality of the placement decision. The gain is largest where memory pressure is highest.
Output unchanged, and the runs verified it.
How the runs were set up →
Fifteen teams fit.
The sixteenth doesn't.
A 70B model at 16-bit precision has 140 GB of weights, so it runs across two 80 GB accelerators and leaves about 20 GB for everything else. One 4,000-token system prompt holds about 1.3 GB of reusable cache state. Fifteen of the applications and teams sharing your servers fit in that budget. The sixteenth exceeds it, before tool schemas, retrieved documents or long conversations are counted.
15 applications or teams · 19.5 GB · fits the budget
20 GB line · the 16th onward exceeds it
More from a fixed hardware budget
The same servers, doing more.
Better use of the memory already in your servers turns hardware you have bought into more usable capacity.
More users at once
Serve more users and applications concurrently from the same hardware.
Longer contexts
Larger retrieved documents, longer conversations and bigger codebases.
Larger models
Serve larger open-weight models at a useful speed.
Defer the next purchase
Push out the next accelerator purchase by getting more from the ones you own.
Your data stays where it is
A short conversation with your security team.
Morphics is designed so that it never needs to see the data it helps manage. It makes placement decisions, and no request content passes through it.
Reads no request contentThe host-side agent reads engine state through interfaces your serving engine already provides. It holds no data and sees no prompts, completions or embeddings.
Never touches the dataThe Morphics MMP decides which tier should hold each piece of data. It is not in the path the bytes travel.
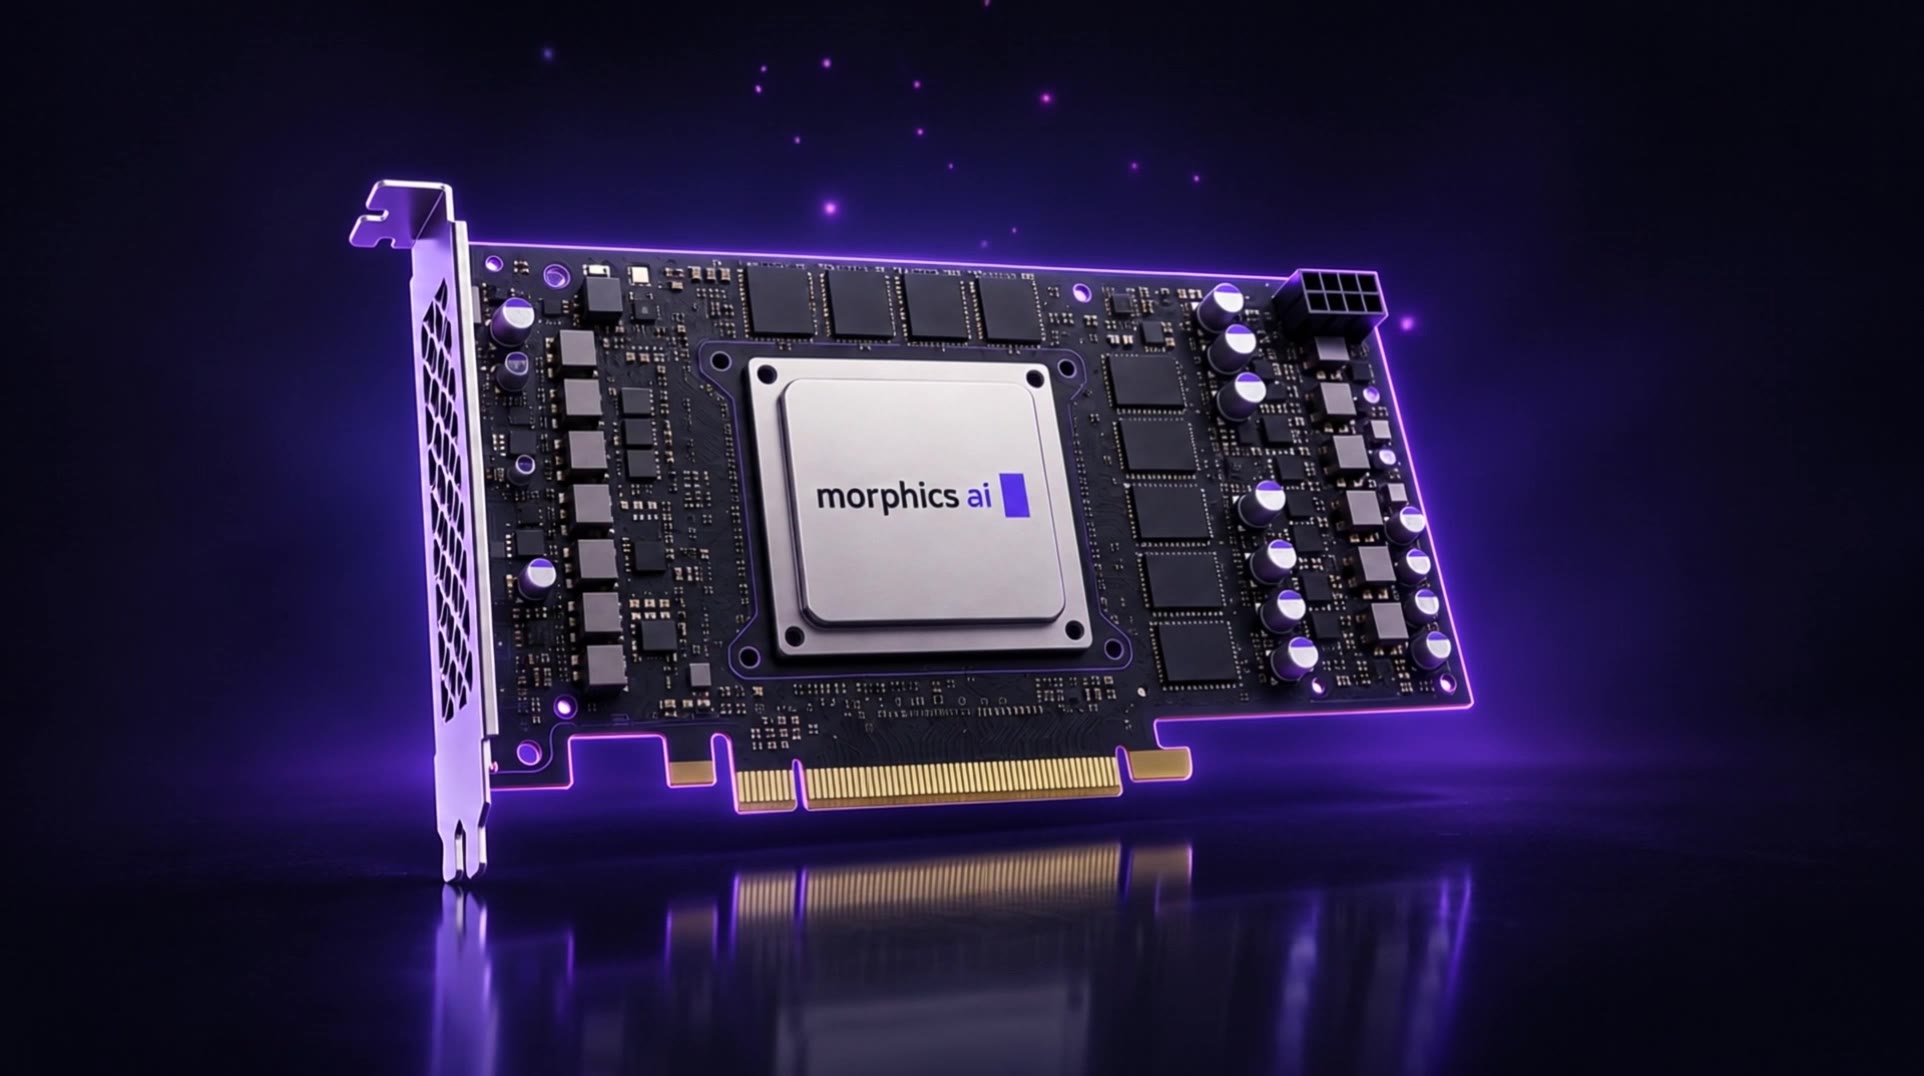
Inside your own serverThe PCIe module installs in your server, in your data center, behind your own access controls.
Advisory, never a commandEvery instruction is version-stamped, and your host validates it before acting and may refuse it. If the MMP stops or is disabled, your engine's own policy runs.
Fits the stack you already run
Your IT team keeps everything it operates today.
Morphics works alongside the serving engine your team already runs. Models, engine versions and application interfaces are unchanged. Nothing about how your infrastructure is built has to change.
How an assessment works
Find out whether memory is limiting your deployment.
Read the counters
A couple of weeks of counters your serving engine already keeps. Nothing is installed in your request path.
Get a written assessment
Whether memory is limiting your deployment. If it isn't, we'll tell you so.
Confirm on your workload
Under real load, on your own hardware, with your current configuration as the control.
Private AI, more capacity
More users, more context, larger models. Same servers.
Talk to us about an assessment on your own infrastructure, or request the white paper for the full technical case.